The right AI for every decision, and a person when it matters.
The FlowSharp decision ladder uses a fast, inexpensive model first, then an LLM, then a person. Every step is traced.
- For
- Process owner
- Compliance
- IT
The problem
Using an LLM for every decision is slow, expensive and hard to explain. Fixed rules are not enough for nuanced cases: a request to classify, a document to verify, a lead to assess. And if the AI answers confidently even when it should not, errors go unnoticed. The choice looks forced between two wrong roads: paying for and waiting on the biggest model even for trivial questions, or hardening everything into rules that break at the first unusual case. In both cases what is missing is what the process owner really needs: knowing which part of the decision was taken by which tool, with how much confidence, and when a human was brought in.
Ladder
- System One · resolves ≈ 70%
- System Two · resolves ≈ 20%
- Person · ≈ 10%
Question → Answer → Confidence → Field
- Urgent complaint? → Yes → 0.91 → urgent
- Valid document? → n/a → 0.52 → undetermined
How it works
1System One decides fast
A decision model answers typed questions (yes/no, classification, score) with a probability, in fractions of a second and at low cost. Up to 20 questions per task, each written to a field of the case.
2Below threshold it does not write
If confidence is below the configured threshold, the value is not written and the field is marked "undetermined". An uncertain value does not enter the case pretending to be certain.
3System Two re-evaluates
An LLM starts again from the original data, without seeing System One's answer, to avoid anchoring. The second opinion is truly independent, not a confirmation of the first.
4If still uncertain, a person decides
Through human fallback. Every decision is tagged system1, system2 or human, so the three origins stay separate in the data, in the indicators and in the history.
Specifications
| Questions per task | up to 20 |
|---|---|
| Question types | yes/no (two thresholds), classification, score (levels or percentage) |
| Test | "Test" button on a real case, without writing data |
| Ladder timeout | 60 seconds overall |
| Context | 24,000 characters preset, up to 1,000,000 |
| Ready-made templates | CV evaluation, lead scoring, request triage, document verification |
| Reuse | presets and assistants prepared by the Admin and chosen by the designer |
| Decisions on documents | text of Library documents, with a preview of the context sent |
An operational example (illustrative values)
The decision ladder orders who decides by cost and risk. In the example, for illustration only, System One resolves about 70% of cases with a simple rule, System Two about 20% with more articulated reasoning, and the person remains for about 10%. Each automatic decision is expressed as a question, answer, confidence and field to write. For example: is the complaint urgent? Answer yes, confidence 0.91, so the urgent field is set. For another question, is the document valid, the answer is not available and confidence is 0.52: the field stays undetermined and the case moves up to the next level. The percentages are not a client's data: they show how the ladder distributes work. The diagram is illustrative and not an official screenshot.
How to verify automatic decisions
To trust a decision ladder you must be able to check every rung. Look at how many decisions stop at each level: if the person receives far more than expected, the low-level rules are too cautious or the data is poor. Then open some decisions: each must show question, answer, confidence and field written, so you understand why the system decided that way. Undetermined values are a sign of honesty, not a flaw: they indicate the system did not pretend to know. Because levels that use AI generate calls, the AI call log shows costs and attribution. For governance, the ladder makes explicit where automation stops and a person takes over, and this boundary is exactly what a reviewer wants to see documented and not left implicit.
Related features
- Human fallback in the same taskIf automation is uncertain or fails, the same task passes to a person: no extra task.
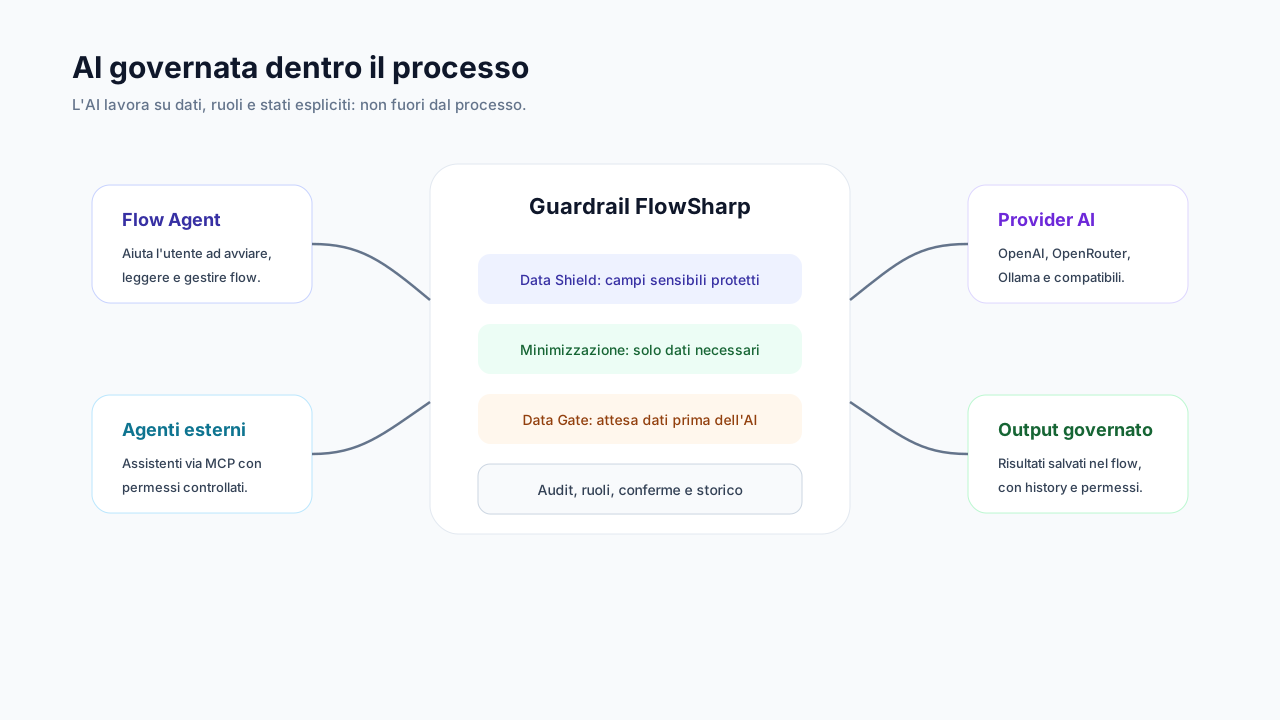
- Data Shield0 sensitive data exposed: reserved fields become placeholders before every AI call.
- AI call logThree logging levels per provider and spend attribution to user, key or Flow Agent.
- Decision metricsAutomatic versus human decisions, fallback rate, escalation rate and system1/system2 split, usable as KPIs.
- AI execution transparencyIn the task detail: model, tokens, duration, shielded values and the question, answer, confidence, field table.
- Generative AI tasksSystem and user prompts, with output to a field or as an outcome.
Use cases
Frequently asked questions
Why two types of AI?
Because deciding and writing are different tasks. The fast model costs little and answers with a probability; the LLM reasons on the hard cases.
Can I test before publishing?
Yes, the Test button runs a real call without modifying the case.
Can I convert a decision that is manual today?
Yes: a manual decision converts into an AI decision while keeping the human fallback.
Does it work in Italian?
Yes. The fast model performs best in English, so questions can be phrased in English even on Italian data.